 n8n Automation Hub
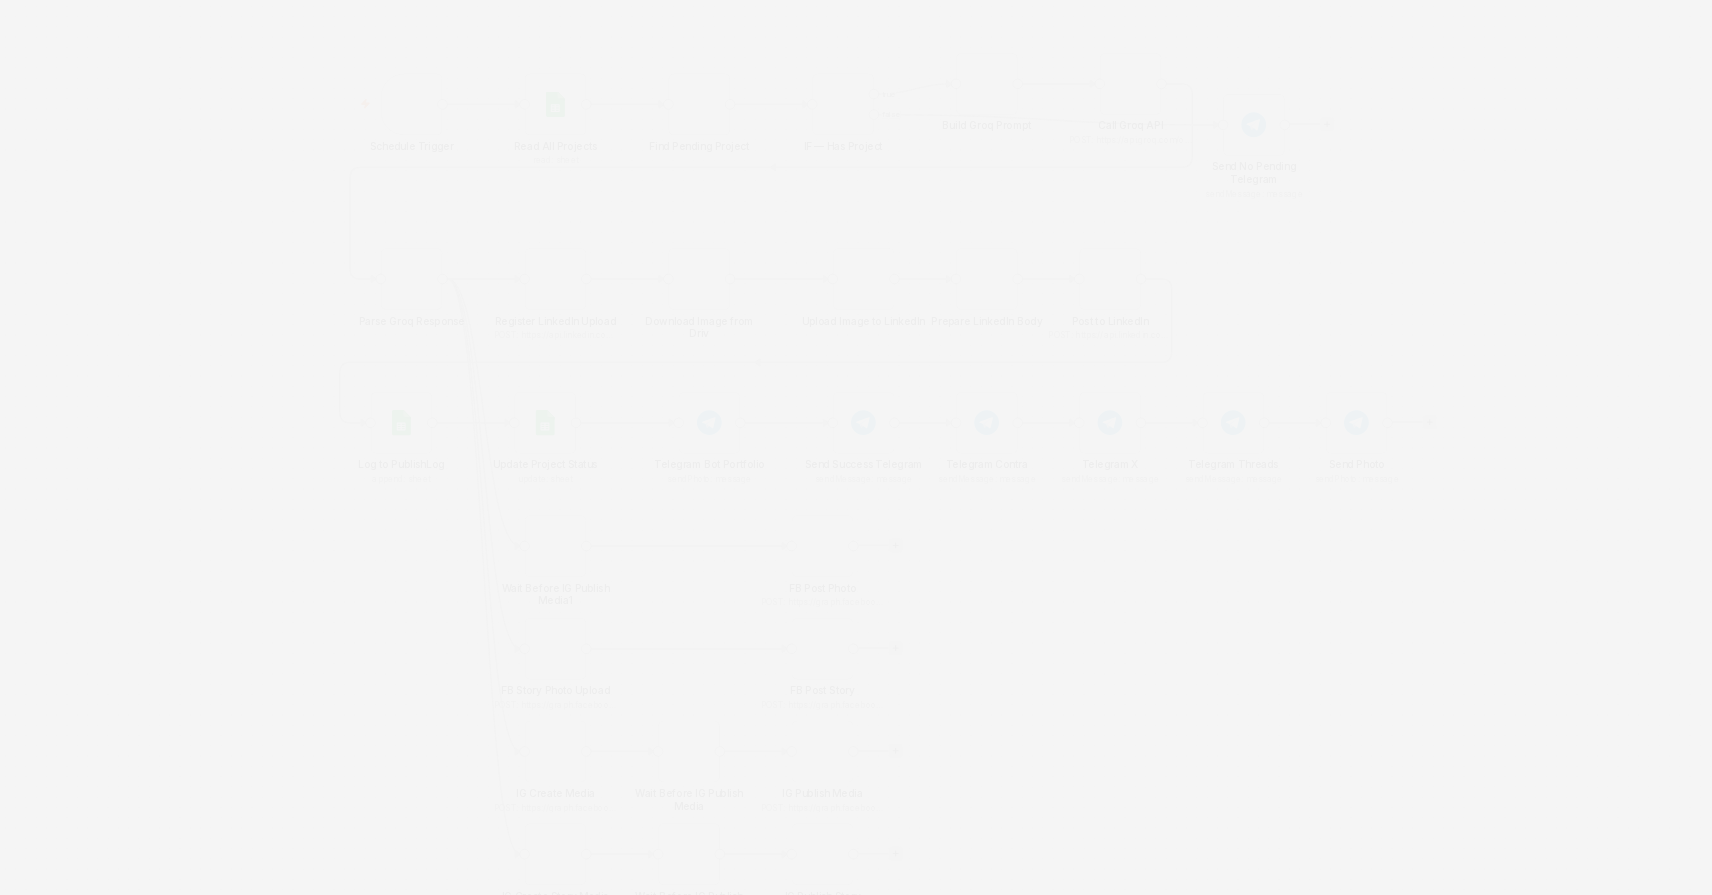
A workflow that reads one row and fans out to seven platforms
This publisher runs once a day, picks the first row marked "pending" from a Google Sheet of portfolio projects, has an LLM write platform-specific posts, then publishes to LinkedIn, X, Threads, Contra, Telegram, Facebook, and Instagram before marking the row done. A long, branching chain by necessity — one project, seven different publish paths, several of which (LinkedIn's image upload, Instagram's story vs. feed post) need multiple nodes of their own.
Where "undefined" showed up
Checking a flagged run, the title and body text were `undefined` in the Telegram summary, the Contra post, the X post, and five more nodes besides — different platforms, same missing value. Every one of those nodes referenced the data it needed with n8n's `$('Some Earlier Node').item` syntax: reach back to a specific named node anywhere in the workflow and grab the item currently being processed.
Why the shortcut stops working
`.item` isn't a direct lookup — it resolves through n8n's pairedItem lineage, the chain of "this output item came from that input item" links each node leaves behind as data flows through. That chain has a practical depth limit. Every one of the nine broken references sat five to eight nodes downstream of the node they were pointing at — Register LinkedIn Upload, Download Image, Upload Image to LinkedIn, Post to LinkedIn, Log to PublishLog, Update Project Status, and the seven publish nodes all reaching back to nodes that far upstream. Close, it resolves fine. Far enough, and `.item` returns `undefined` with no error thrown — just silently wrong.
The fix, and why it's safe here
Replaced every `.item` reference in the workflow with `.first()` — get the first item from that node's output, full stop, no lineage tracing involved. That's only a safe substitute when a node genuinely emits one item per run, which this workflow does: it never batches, never splits, one project per execution. A workflow that fans out to multiple items per run would need a different fix, because `.first()` would then silently grab the wrong item just as confidently as `.item` grabbed nothing.
The second bug hiding behind the same symptom
Once the undefined values cleared, a real content bug was still there underneath: the Facebook and Instagram posts were never broken by the reference bug at all — they were built from `post_title + linkedin_text` reused verbatim, because nobody had ever given those two platforms their own generated copy. Fixed by adding dedicated Facebook and Instagram fields to the LLM's output schema and pointing those two nodes at their own text instead of borrowing LinkedIn's.
What to check if this pattern looks familiar
Any n8n workflow with a `.item` reference reaching back more than two or three nodes is a candidate for this exact failure, and it won't announce itself — the execution log shows green, the value is just quietly wrong. `.first()` (single-item workflows) or `.first()`/explicit indexing tied to the actual upstream node reference (multi-item workflows) are both safer than trusting pairedItem tracing across a long chain.
.item, .first(), .all() and itemMatching(): when to use which
| Expression | Returns | Use when |
|---|---|---|
$('Node').item | The item linked to the current one through pairedItem | Multi-item workflows with a short, simple chain |
$('Node').first() | The first output item of that node | The node always outputs exactly one item |
$('Node').all() | All output items of that node | Aggregating, or looking up by a key in a Code node |
$('Node').itemMatching(i) | The linked item for input index i (Code node) | Code nodes that loop over items and need each one's origin |
Why the lineage can get lost
Each node records which input item produced each output item. .item follows that record backwards, hop by hop. It breaks when one of the nodes in between doesn't record it properly, which is common with:
- Code nodes that build new items without returning a
pairedItemfor them - Nodes that merge, aggregate or split items
- HTTP Request nodes that return several items from one input, such as pagination
So the problem in this workflow was most likely not the distance itself, but that the longer the chain, the more likely one node in it doesn't pass the lineage on. The practical result is the same: the further back a .item reference reaches, the more likely it is to resolve to nothing.
Making lineage explicit in a Code node
When a Code node creates new items, it can state where each one came from:
return $input.all().map((item, i) => ({
  json: { ...item.json, caption: makeCaption(item.json) },
  pairedItem: { item: i },
}));
This keeps .item working for every node after it. In a single-item workflow like the portfolio publisher, .first() is still the simpler and more robust option.
How to find risky references
Search the workflow JSON for ').item and, for each hit, count the nodes between the reference and the node it names. Anything more than a few hops away, or crossing a Code, Merge or Split node, is worth replacing or testing with a real multi-item run.
Frequently asked questions
Why does $('Node').item return undefined in n8n?
It follows the pairedItem lineage back to the named node. If any node in between doesn't pass that lineage on, the lookup finds nothing and returns undefined without an error.
Is .first() a safe replacement for .item?
Only if the referenced node always outputs exactly one item per run. In multi-item workflows .first() silently returns the wrong item for every item but the first.
How do I keep pairedItem working through a Code node?
Return a pairedItem entry with each new item, for example pairedItem: { item: i }, pointing at the input item it was built from.
How can I find fragile references in a workflow?
Search the workflow JSON for ').item' and check how many nodes, and especially which Code, Merge or Split nodes, sit between the reference and its source.