 n8n Automation Hub
What a routine update actually looks like
n8n on this box runs as a plain Docker container, not docker-compose, so an update means pulling the new image and recreating the container with the same volumes, environment variables, and port mapping — the workflow data itself lives in a separate named volume, independent of the container's own lifecycle. Pull, stop, remove, run again with the same flags, confirm the API responds. That part went exactly as expected.
The check that almost didn't happen
Out of habit more than suspicion, the active-workflow count from before the update got compared against the count after. Before: 34. After: 33. Nothing in the startup log had flagged an error, and the API health check had already come back green — the only reason this surfaced at all was a manual before-and-after comparison that isn't part of a normal health check.
What the new version had actually changed
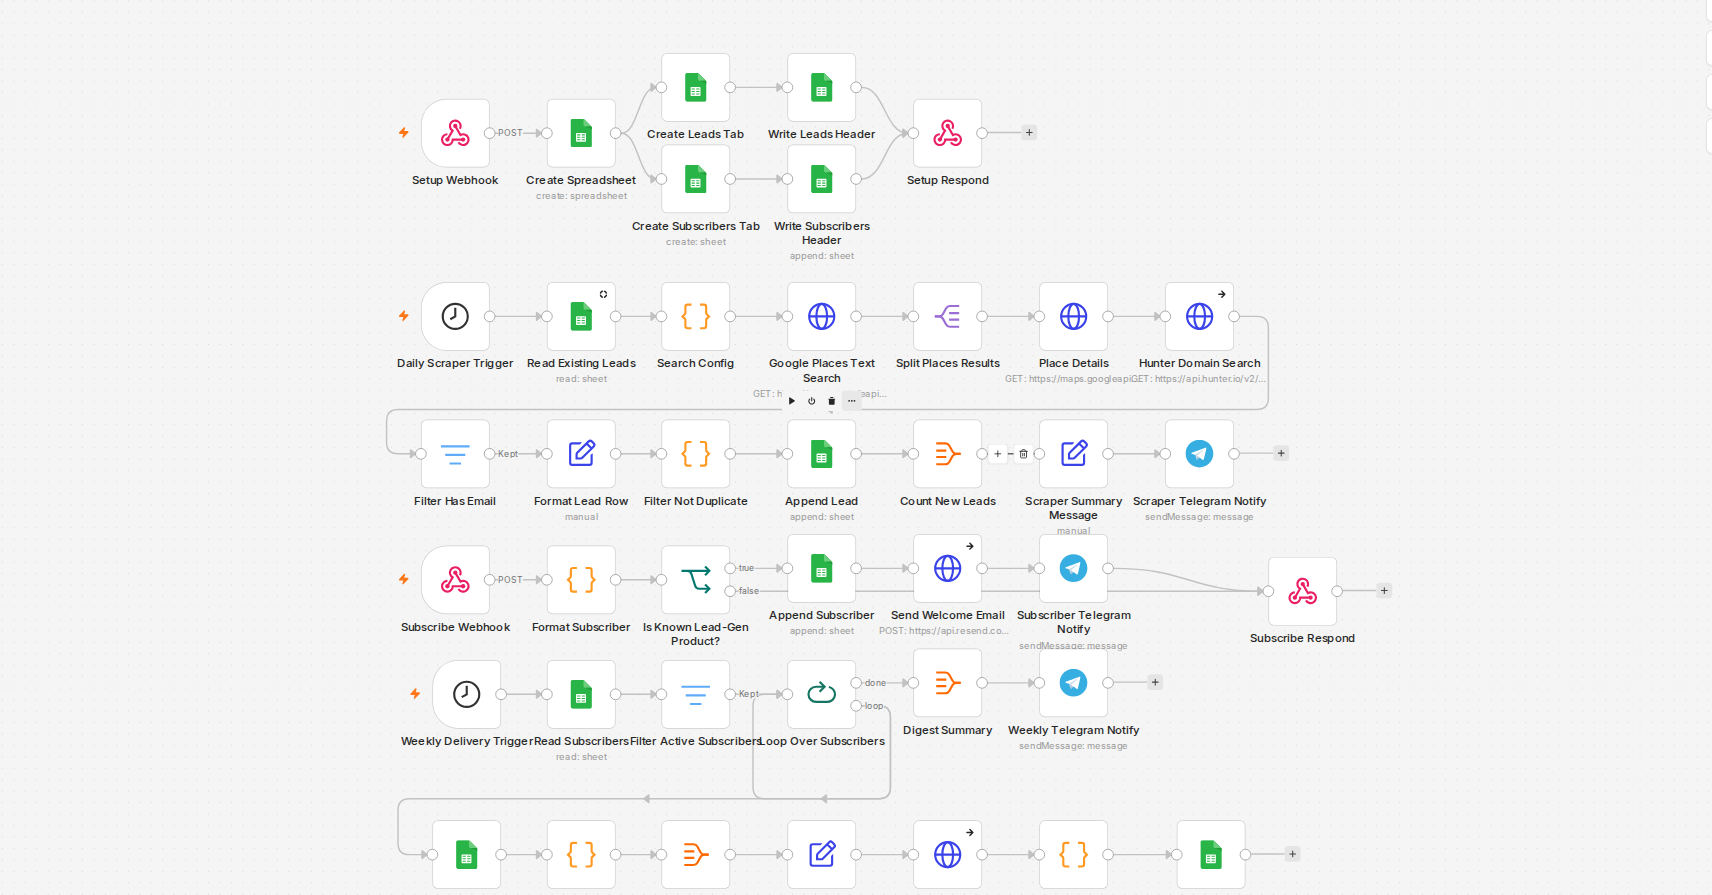
This version's release included database migrations affecting how schedule triggers are stored internally. One specific schedule-triggered lead-gen workflow got flipped to `active: false` by that migration — not a crash, not a corrupted workflow, just quietly turned off as a side effect of the schema change. It would have simply never run again, silently, until someone happened to notice its daily output had stopped.
The fix was almost anticlimactic
A single `POST` to the workflow's activate endpoint turned it back on immediately — no data loss, no reconfiguration, count back to 34. The hard part was never fixing it; it was noticing it needed fixing at all, since every other signal available said the update had gone perfectly.
A second, unrelated mistake from the same job, worth keeping separate
Earlier in the same update process, the container recreate command got run *through* an n8n workflow using an SSH-node shortcut — which meant the `docker stop` command was executed by a process running inside the very container it was told to stop. The stop succeeded, killed its own execution before it reached the following `rm`/`run` commands, and left the container stopped but never recreated. Recoverable by finishing the remaining commands manually from outside, but the actual lesson is narrower than "be careful with docker": any command that touches a container's own lifecycle needs to run from somewhere that isn't inside that same container, full stop.
What to check after any future update
Snapshot the active-workflow list before updating, compare it after — not just whether the API responds, but the actual count and which ones are active. A version bump that touches internal schema or trigger storage can deactivate something without logging an error, and a clean startup log is not the same claim as "nothing changed."
A before-and-after check you can script
The count comparison in this story is easy to automate, and it is worth doing every time. The n8n API can filter the workflow list by state. On my instance GET /api/v1/workflows?active=true&limit=250 returned only active workflows, all 43 of them in a single page with no next-page cursor at that moment. Save the list before the update, save it again after, and compare:
curl -s -H "X-N8N-API-KEY: $KEY" "$BASE/workflows?active=true&limit=250" \
  | python3 -c "import json,sys; print('\n'.join(sorted(w['id']+' '+w['name'] for w in json.load(sys.stdin)['data'])))" \
  > active_before.txt
# ...update n8n, wait until it is healthy, run the same command into active_after.txt...
diff active_before.txt active_after.txt
Any line the diff shows is a workflow whose state changed during the update. Two notes: jq is not installed on my box, which is why the example uses Python (use jq if you have it), and if you have more workflows than one page holds, follow nextCursor until it is empty, otherwise the comparison misses the tail.
Turning it back on
Reactivation is one call per workflow: POST /api/v1/workflows/{id}/activate, and the response contains active: true when it worked. I use the same call in throwaway test workflows and it behaves identically. After reactivating a schedule-triggered workflow, look at its next run rather than assuming: a trigger that was rewritten by a migration deserves one observed firing.
What this does not catch
A matching list only proves that the same workflows are switched on. It does not prove that credentials, webhook URLs or schedules still behave the same, so keep one real scheduled run in the first day after an update as a second check.